Journal of System Simulation ›› 2026, Vol. 38 ›› Issue (10): 2905-2923.doi: 10.16182/j.issn1004731x.joss.26-0399
• Intelligent Optimization Algorithms and Autonomous Decision?Making • Previous Articles Next Articles
Zhang Yonghao, Xue Changyou, Fan Xueman, Cheng Zhuo
Received:2026-04-30
Revised:2026-06-30
Online:2026-10-31
Published:2026-10-20
Contact:
Xue Changyou
CLC Number:
Zhang Yonghao, Xue Changyou, Fan Xueman, Cheng Zhuo. Cooperative Hunting Method for Multiple USVs Based on Improved MADDPG[J]. Journal of System Simulation, 2026, 38(10): 2905-2923.
Fig. 1
Task scenario
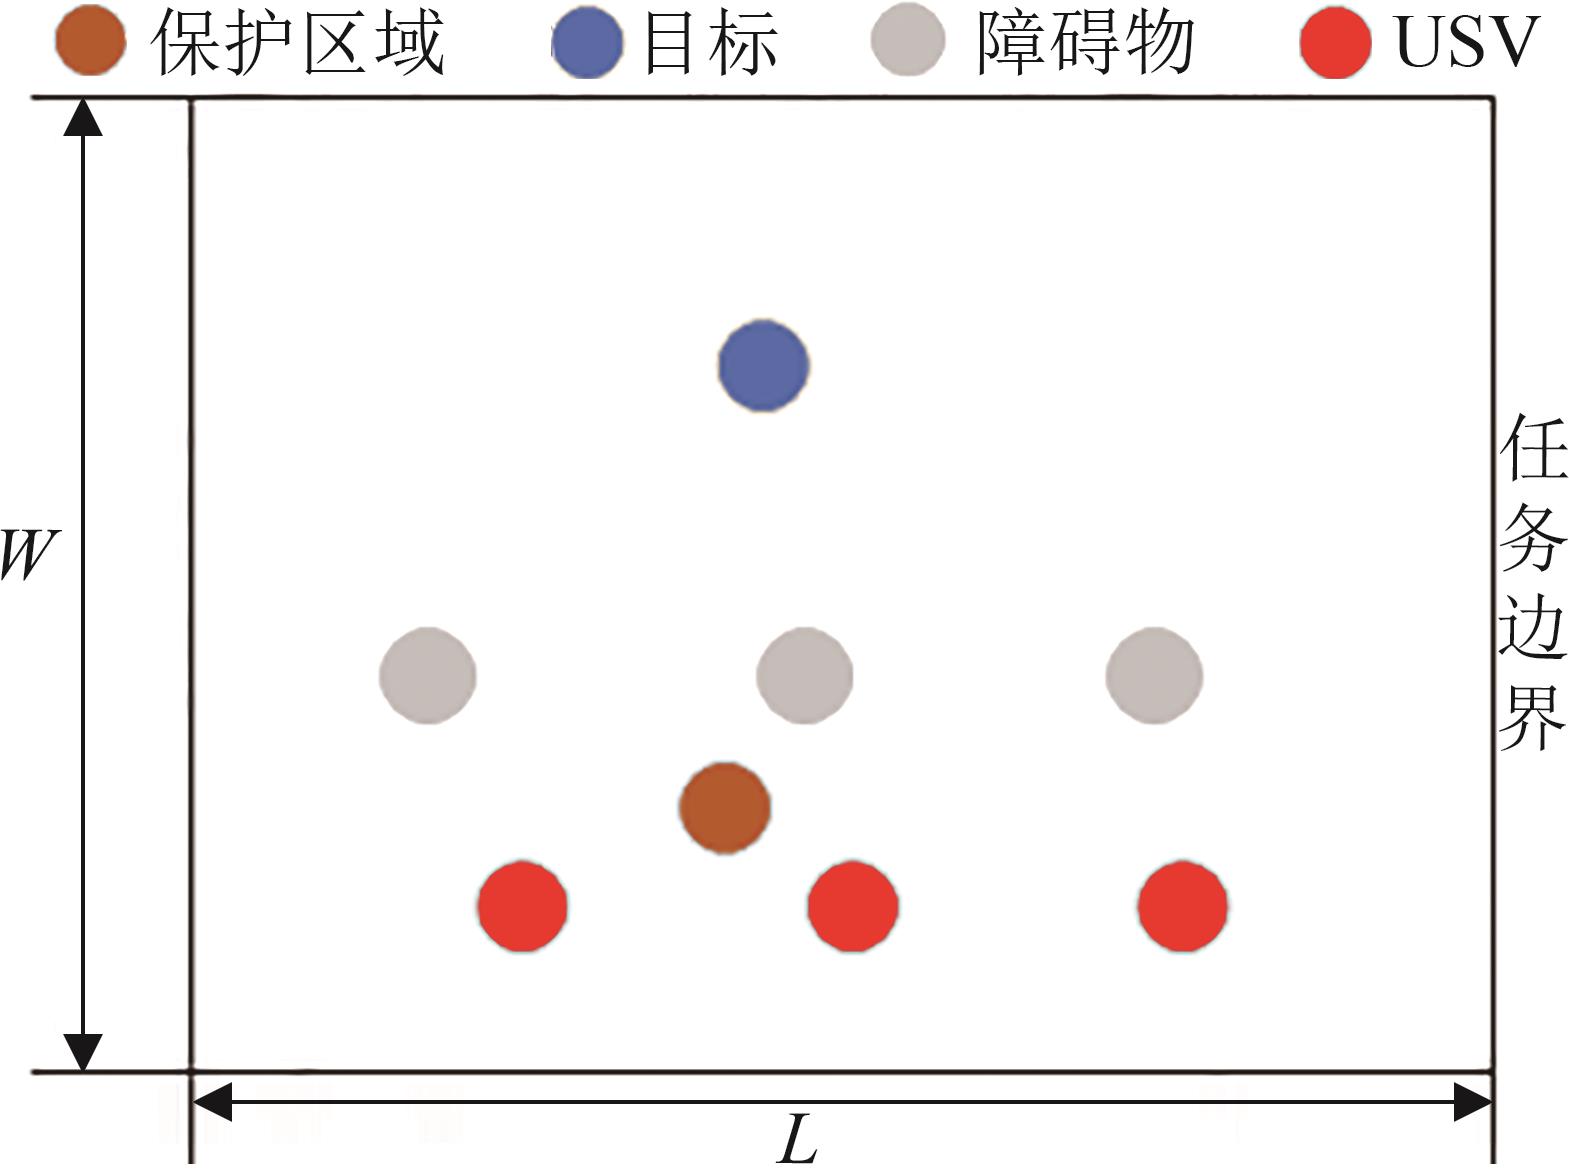
Fig. 2
USV motion model
Fig. 3
USV detection model
Fig. 4
Apollonius circle
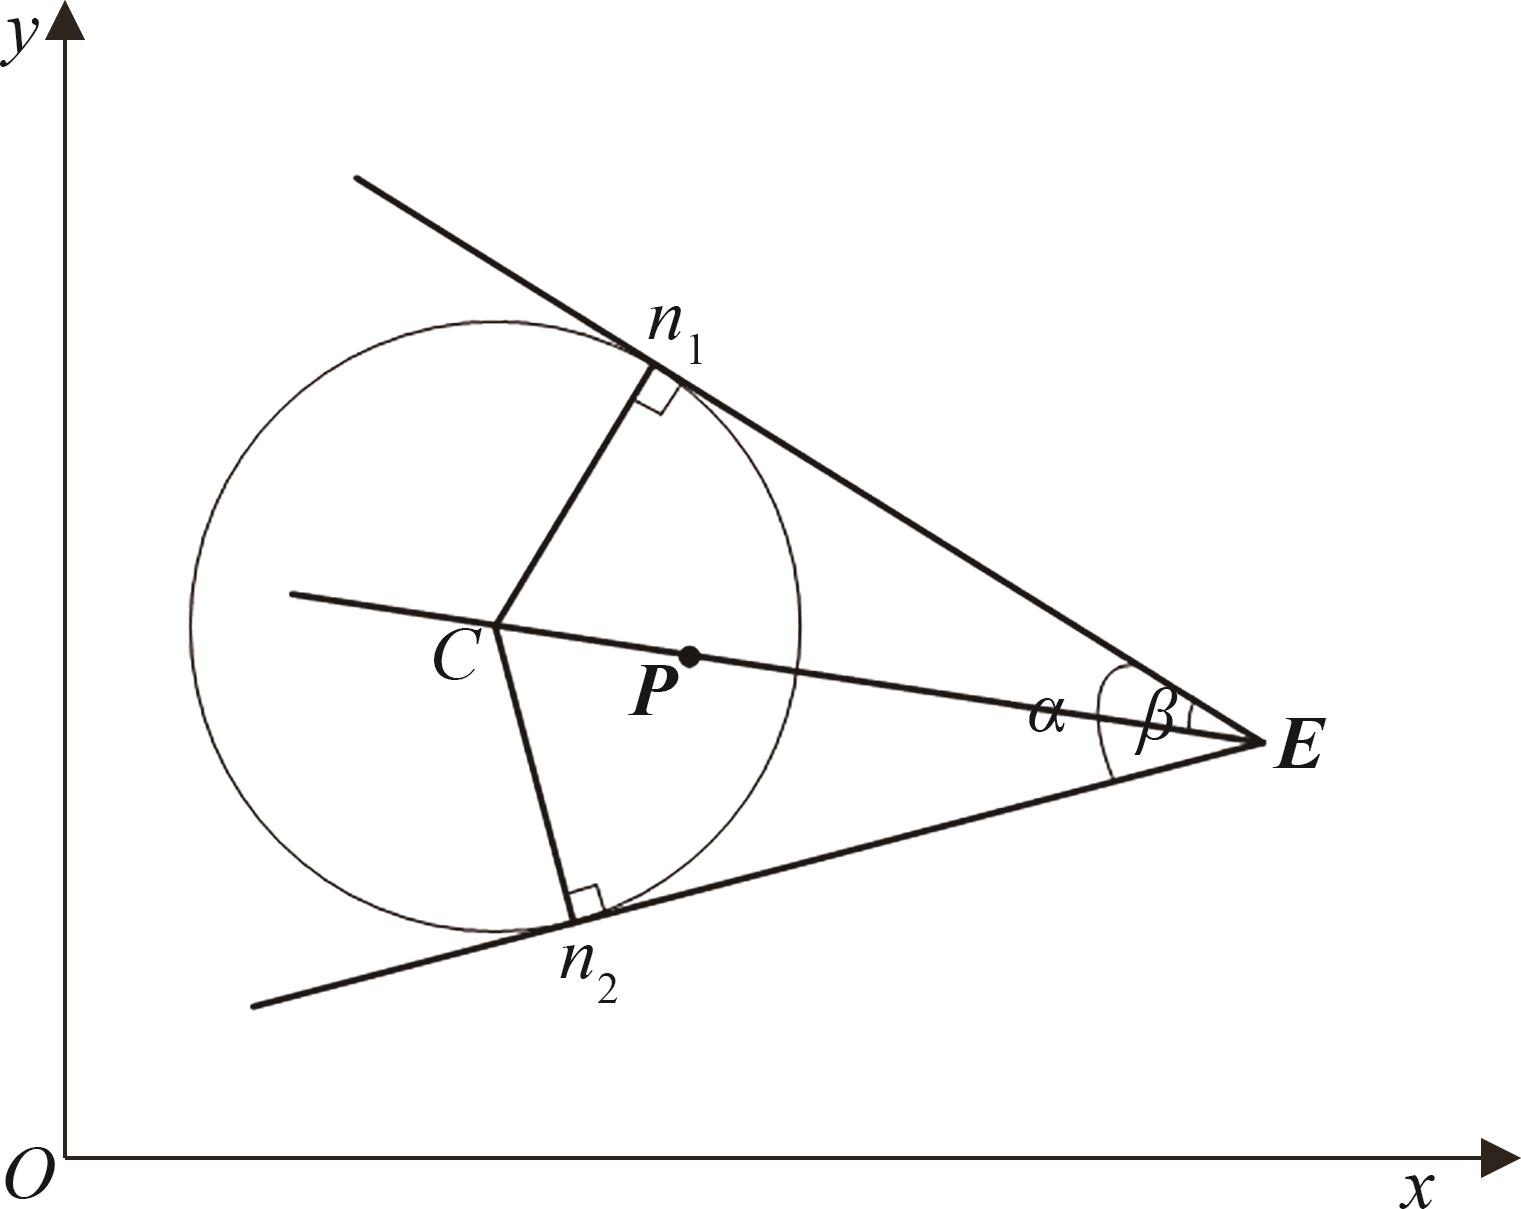
Fig. 5
Successful hunting
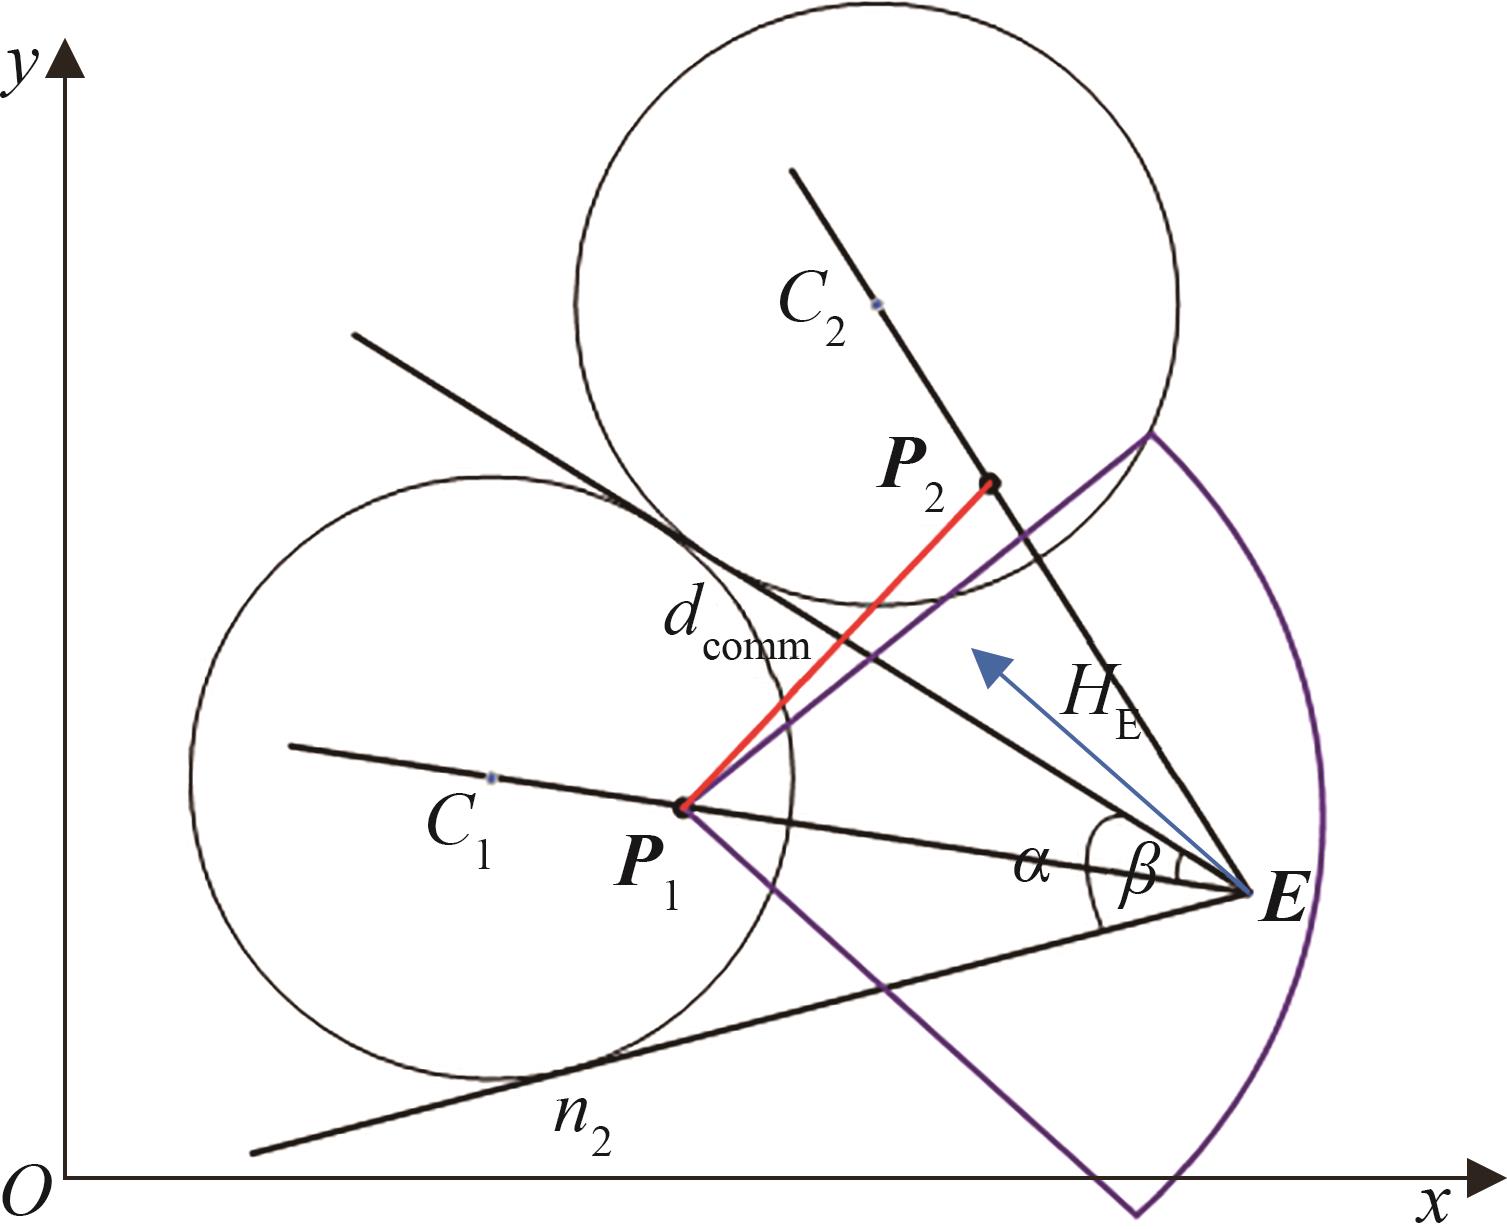
Fig. 6
Target escape strategy
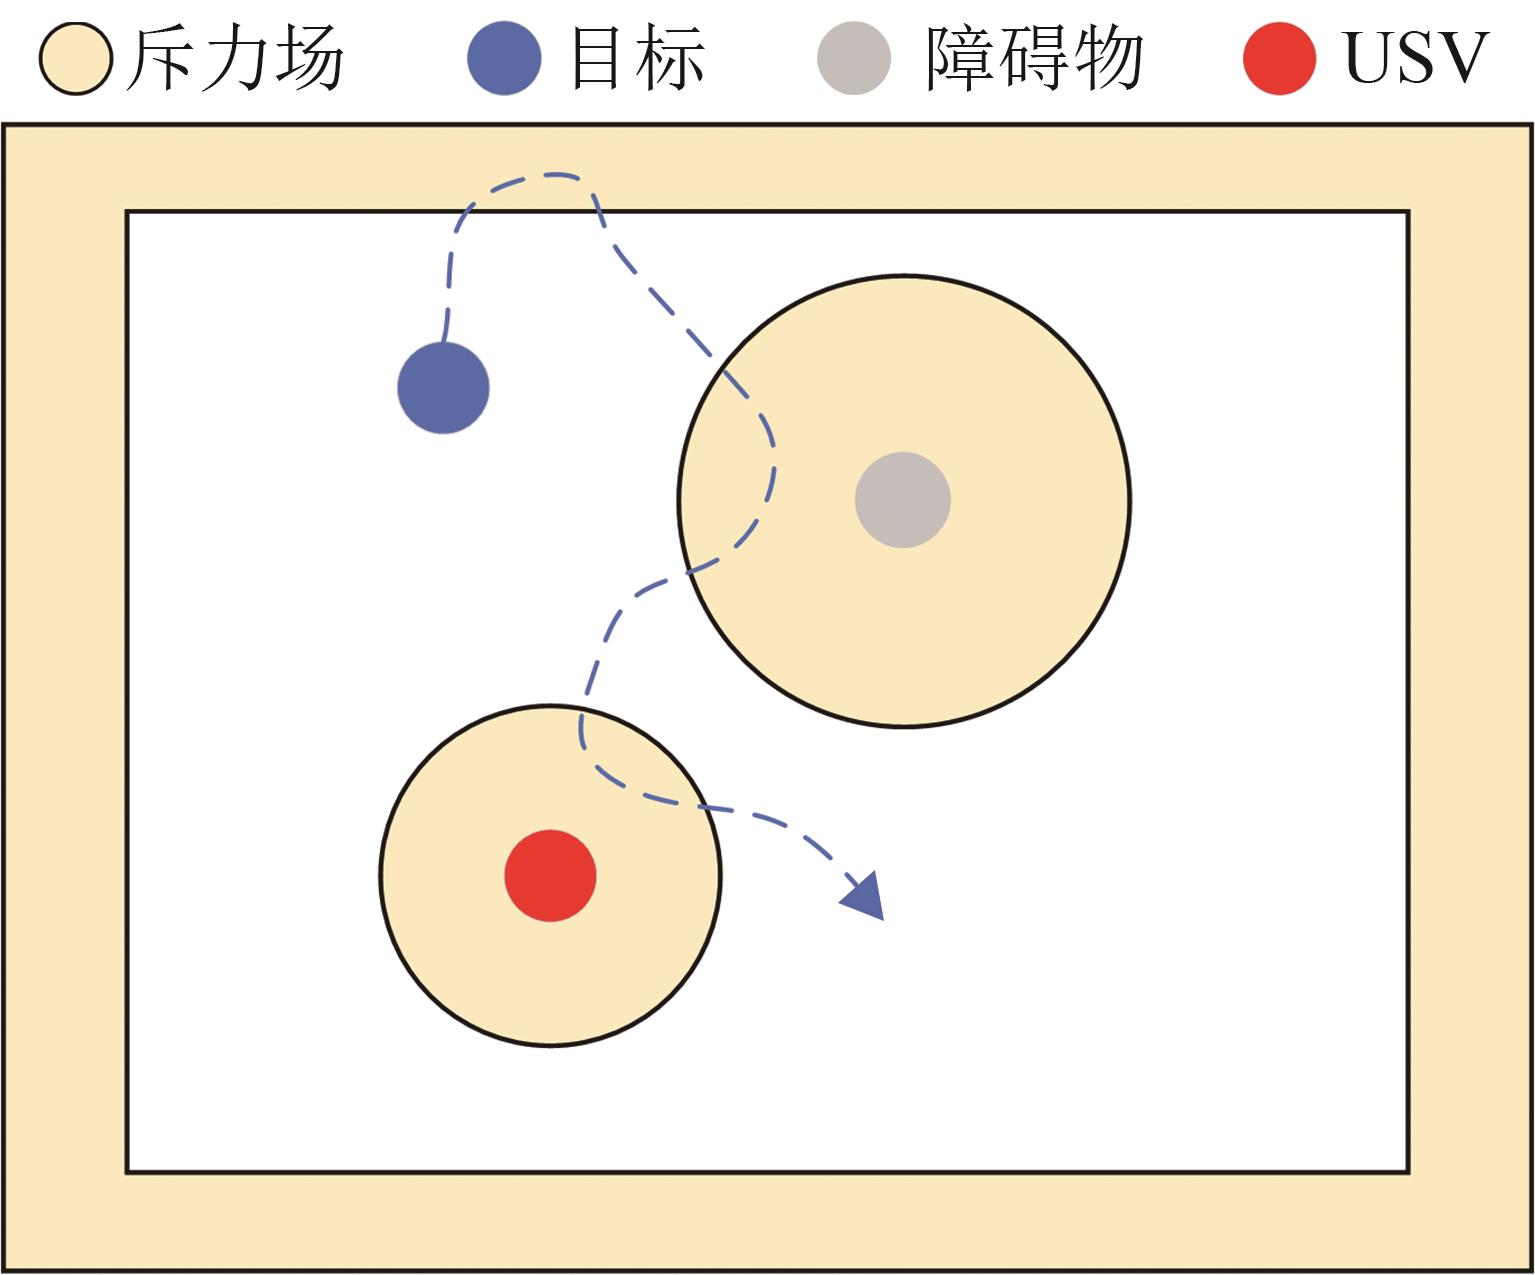
Fig. 7
MADDPG algorithm framework
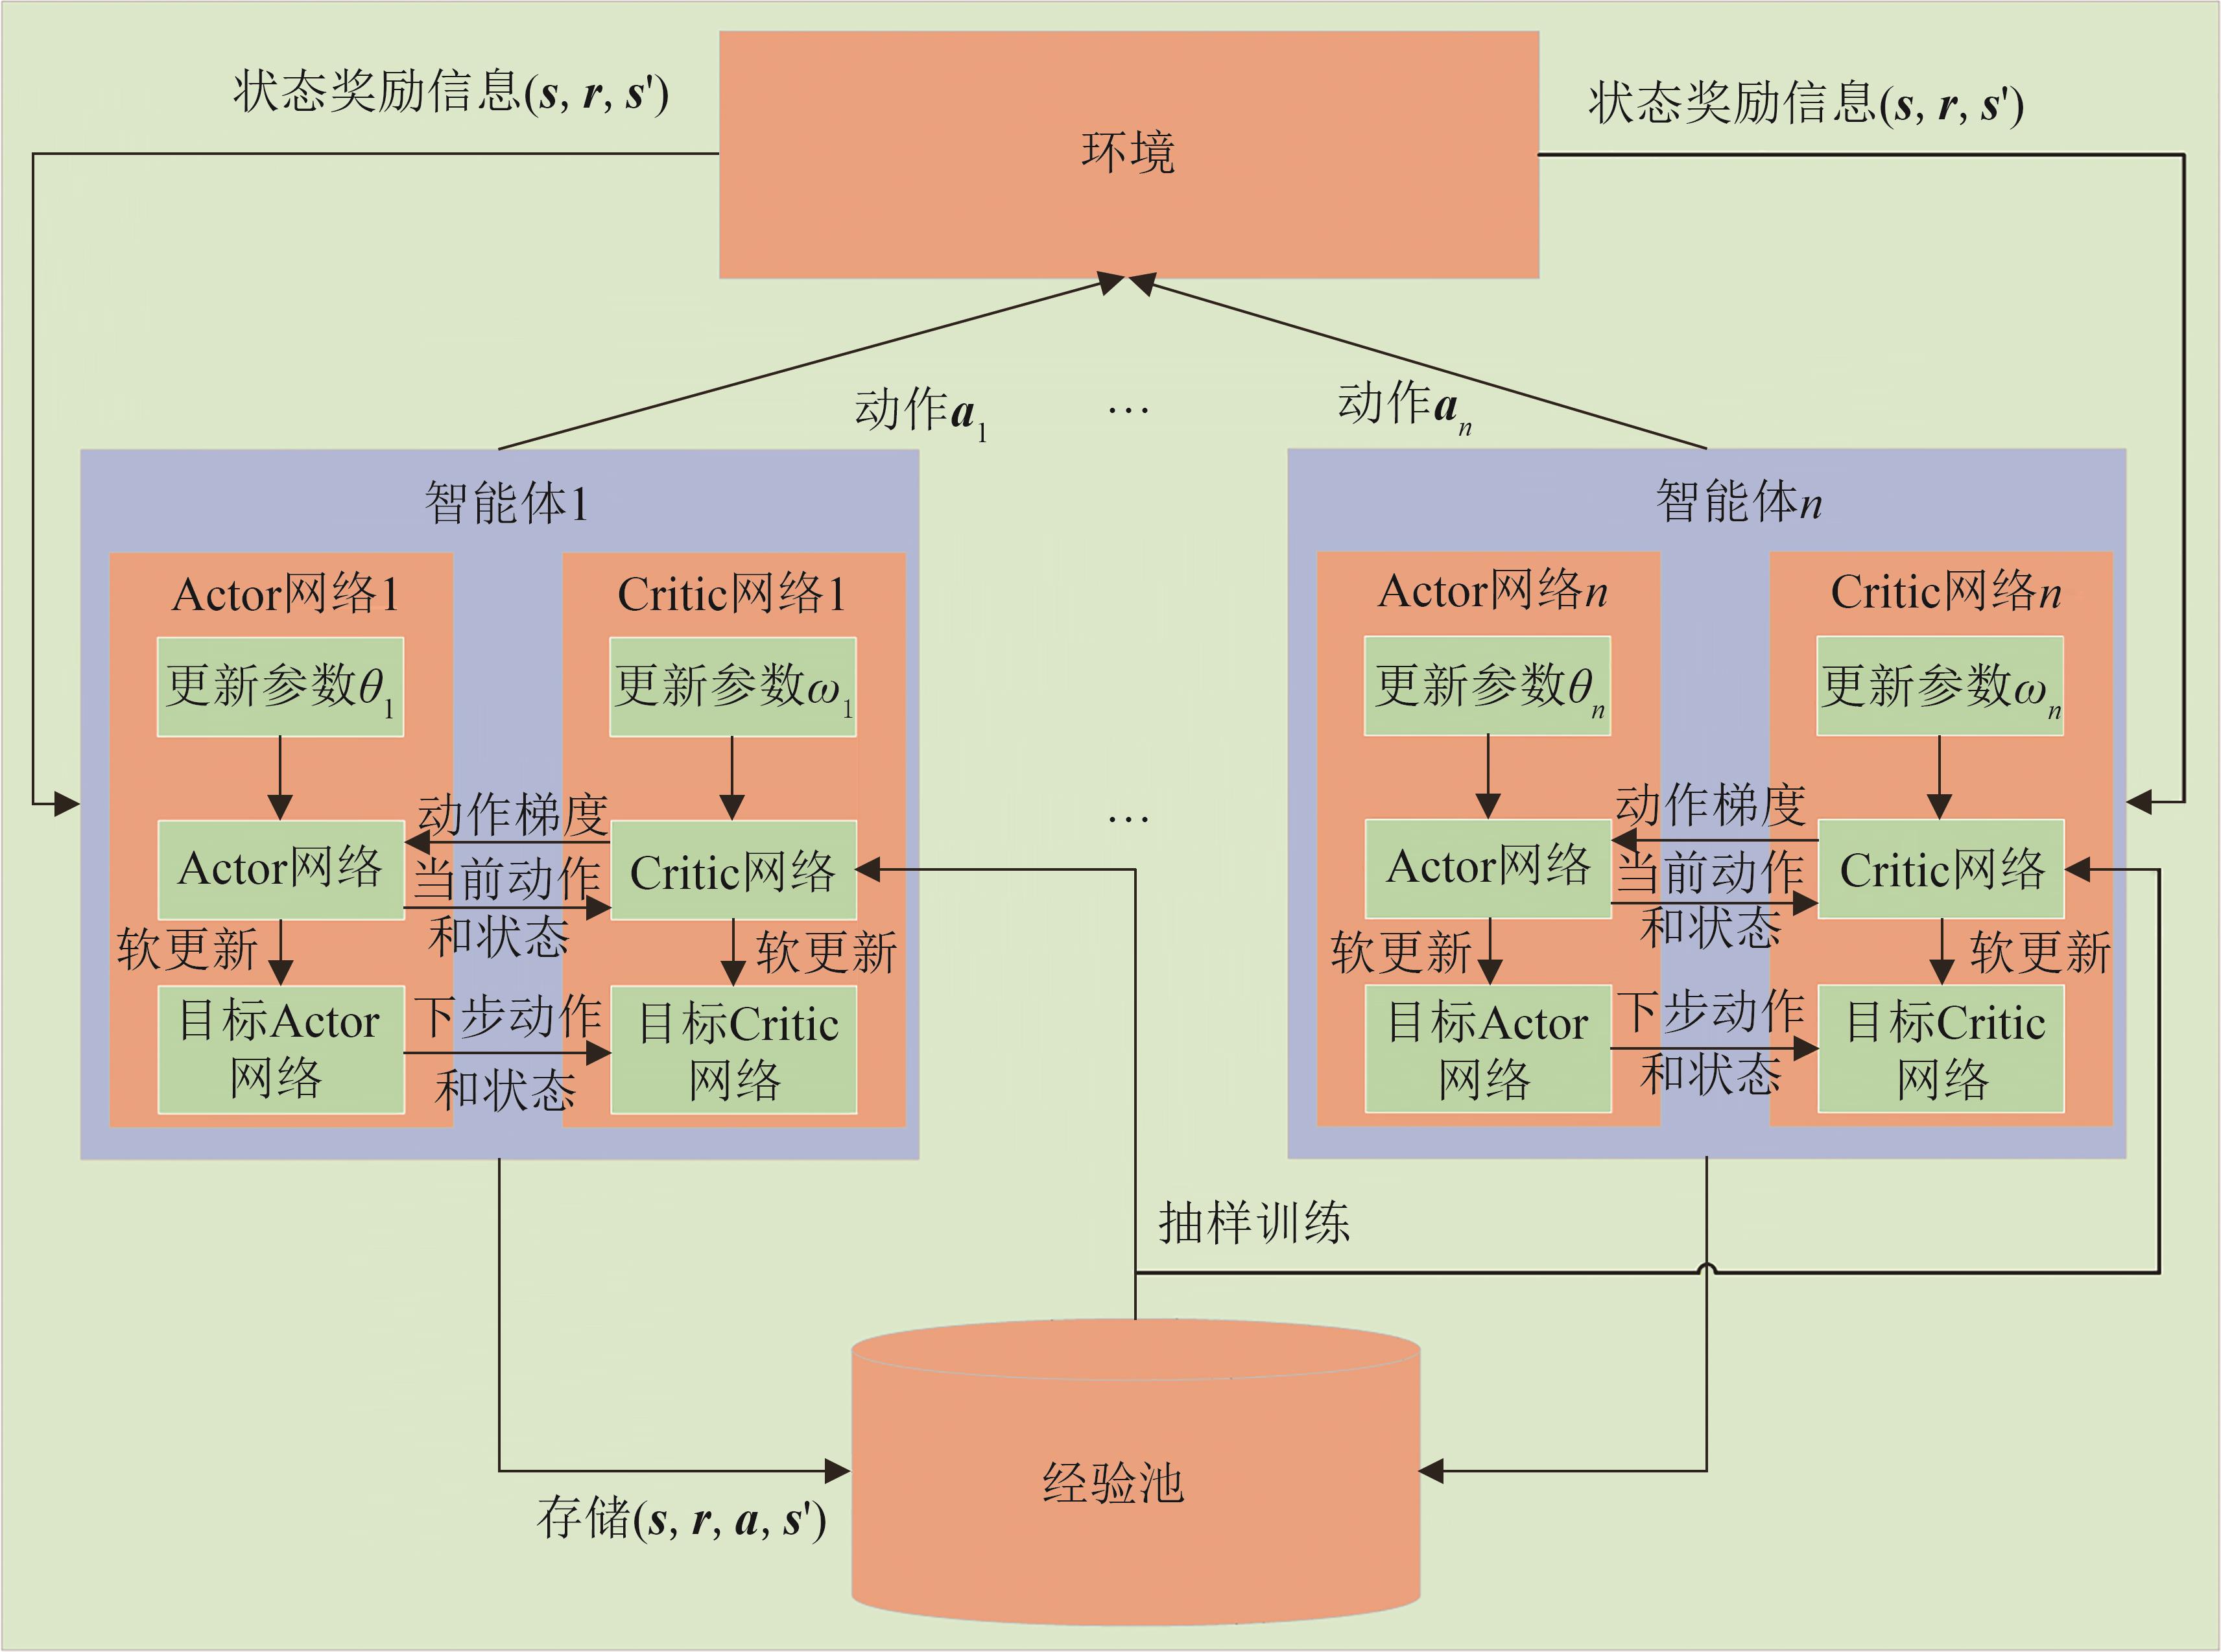
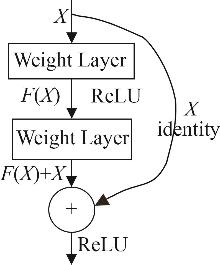
Fig. 8
ResNet residual network
Fig. 9
Actor and Critic network structures
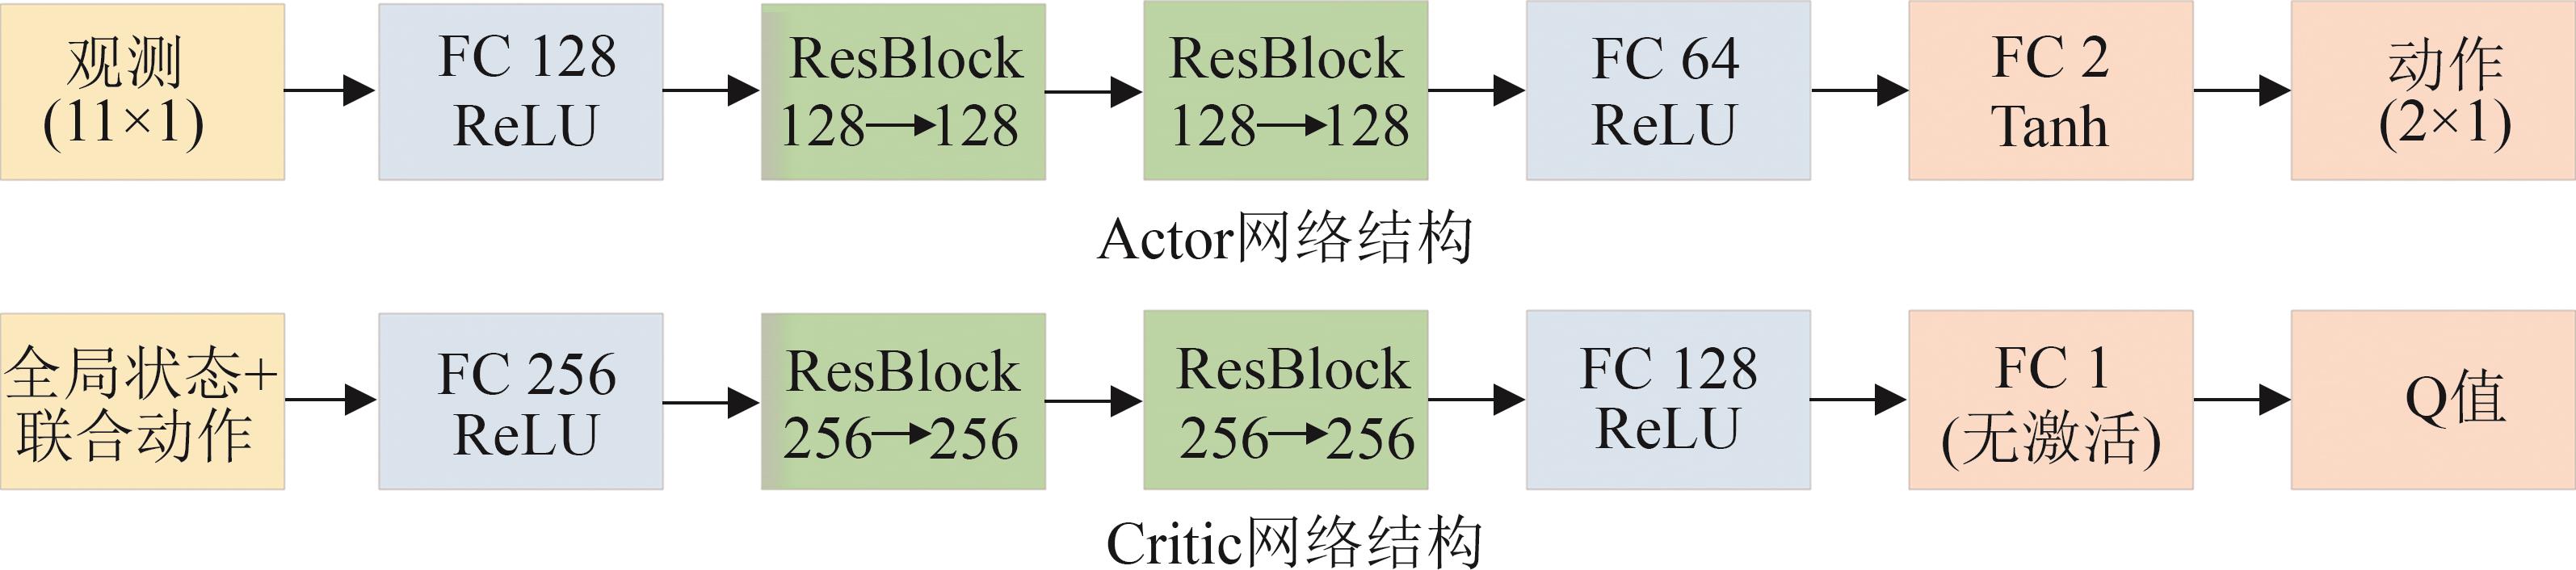
Fig. 10
Overall framework of improved MADDPG-based multi-USV cooperative hunting
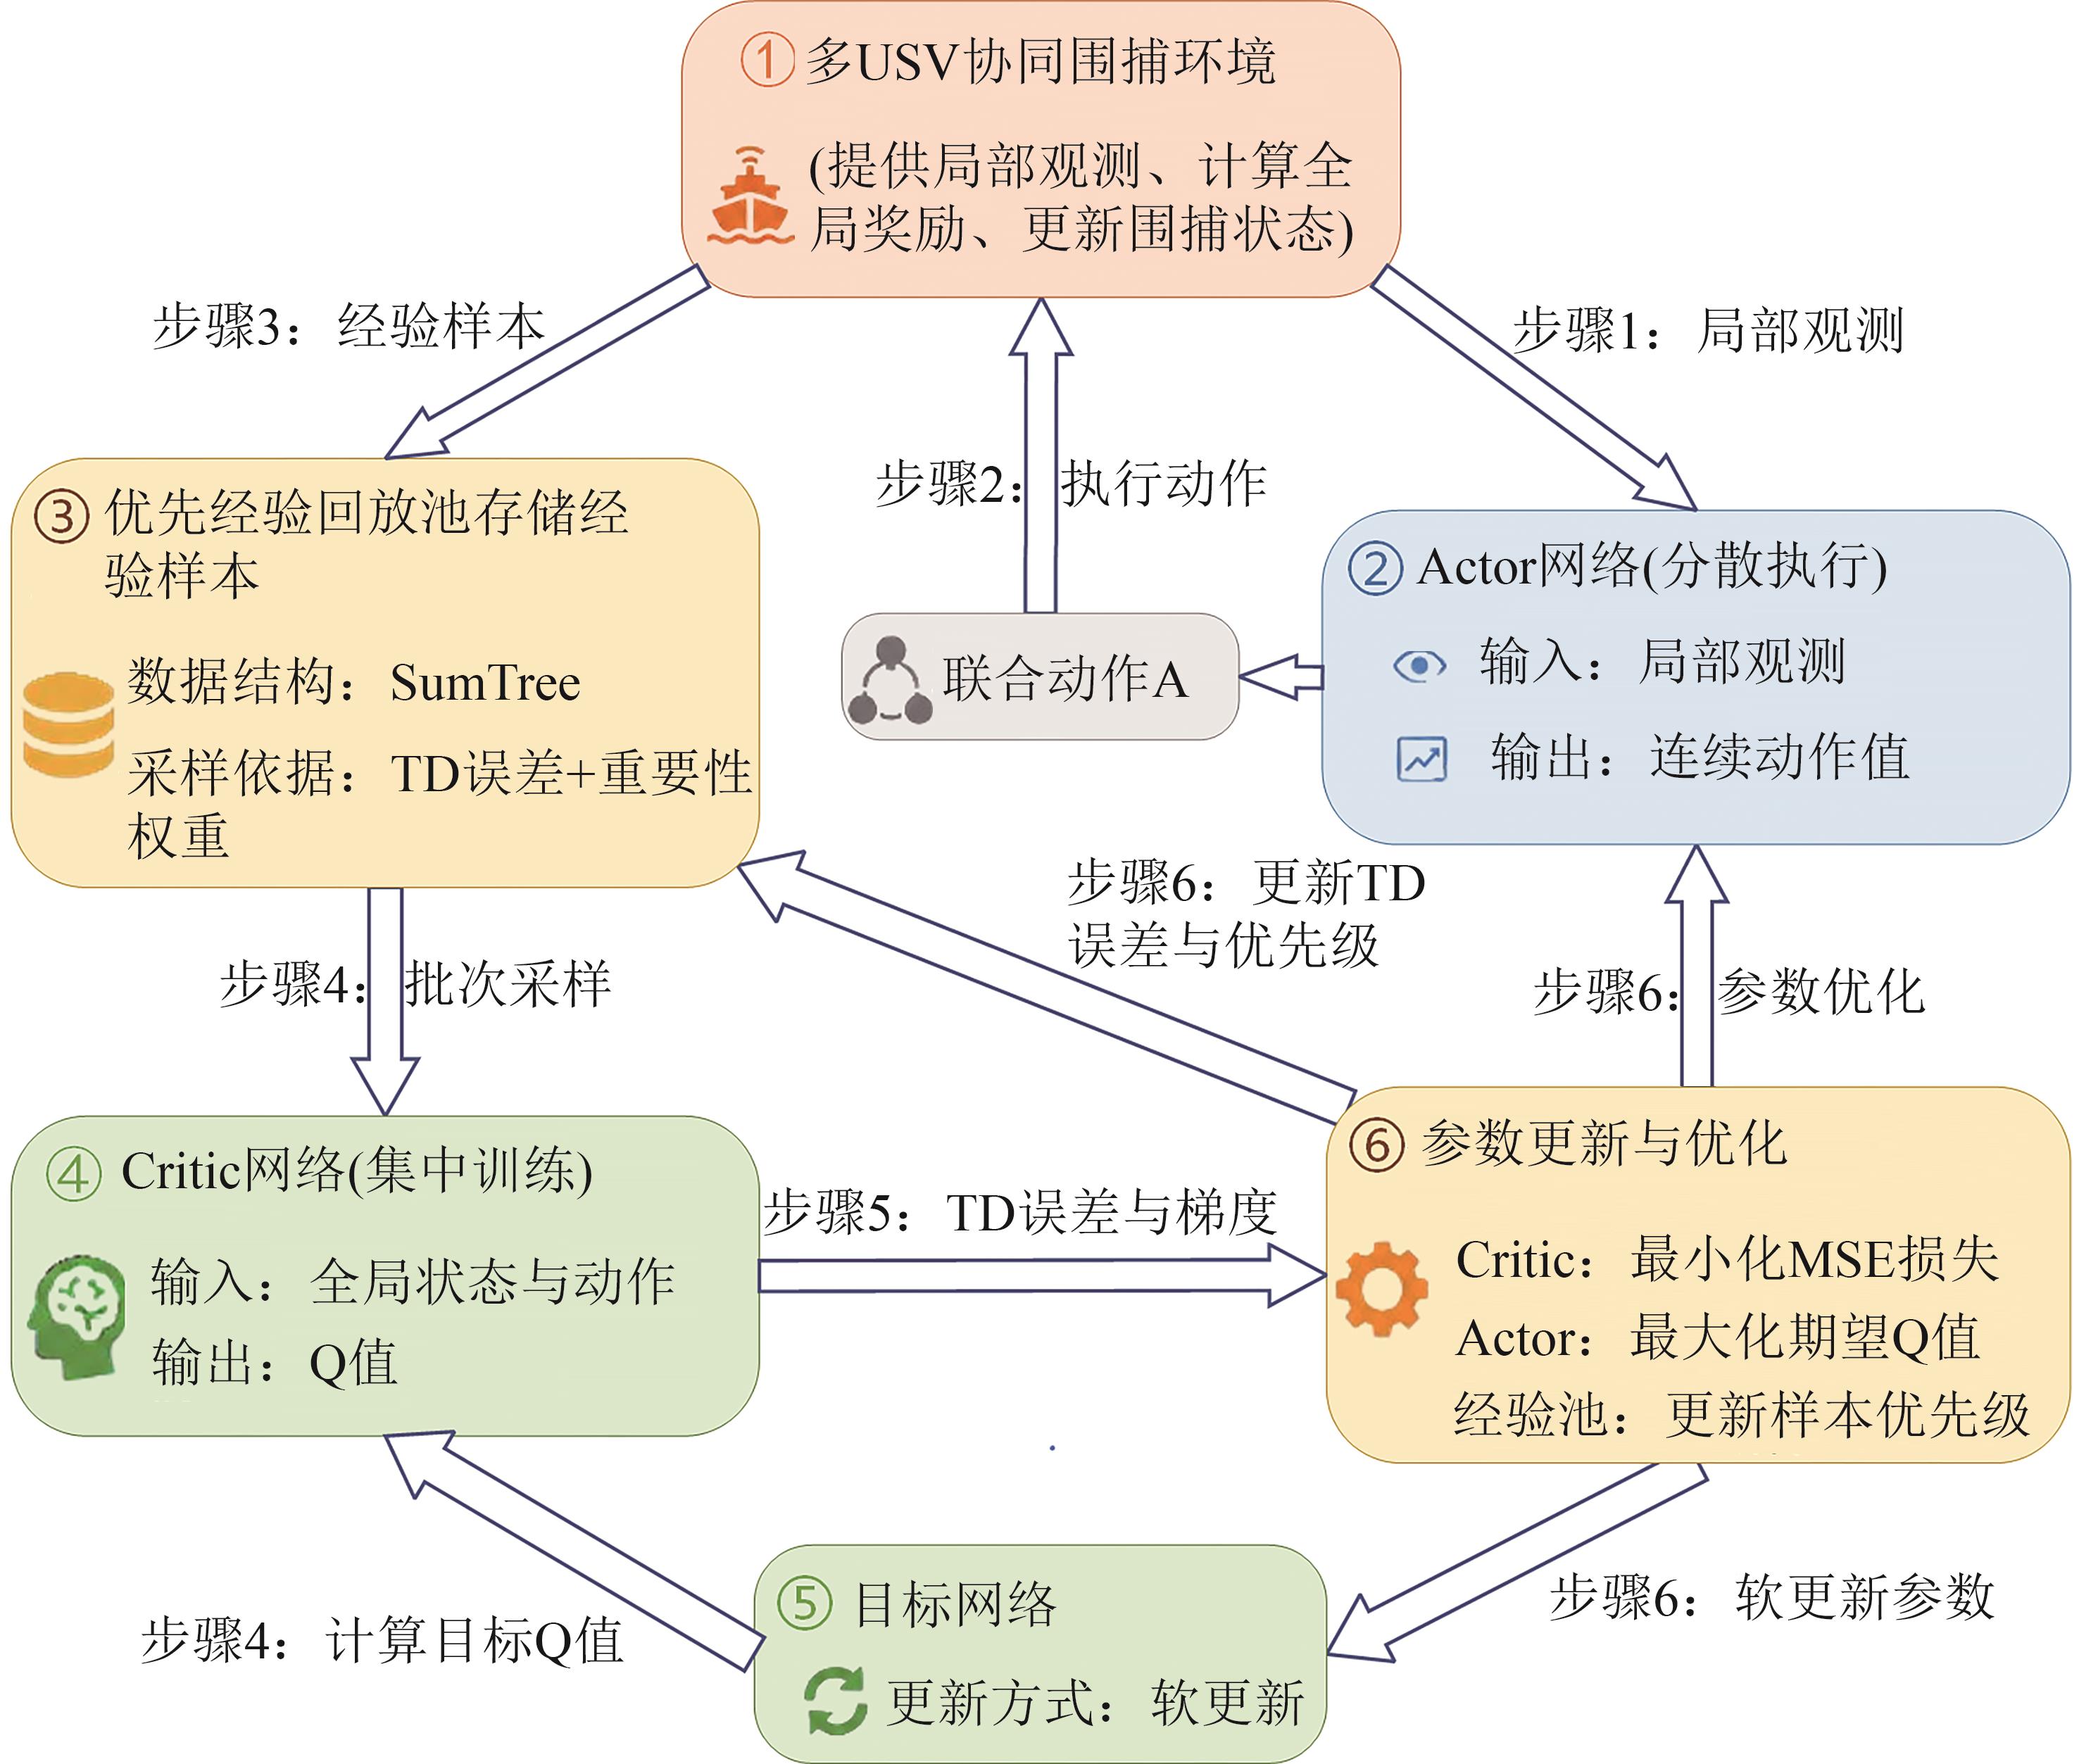
Table 1
Main hyperparameter settings for training
| 训练超参数 | 超参数符号 | 数值 |
|---|---|---|
| 经验池大小 | Memory_Size | 1×10⁶ |
| 批量大小 | Batch_Size | 256 |
| 最大回合数 | Max_Episode | 3×10⁴ |
| 每回合最大步数 | Max_Step | 250 |
| Actor网络学习率 | 1e-5 | |
| Critic网络学习率 | 0.001 5 | |
| 软更新参数 | 0.01 | |
| 折扣因子 | 0.99 |
Table 2
Attribute parameters of environment and USV
| 环境和USV属性 | 参数 |
|---|---|
| 任务区域范围 | |
| 保护区域范围 | |
| USV概率捕获范围 | 10 |
| USV精准捕获范围 | 6 |
| USV数量 | 3 |
| USV初始位置 | |
| USV速度范围 | [ |
| USV初始航向/(°) | 0 |
| 目标探测范围 | 14 |
| 目标初始位置 | (160, 285)服从正态分布 |
| 目标速度范围 | [ |
| 目标初始航向 | [170°, 200°]服从均匀分布 |
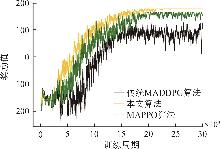
Fig. 11
Average rewards of different algorithms varying with training rounds
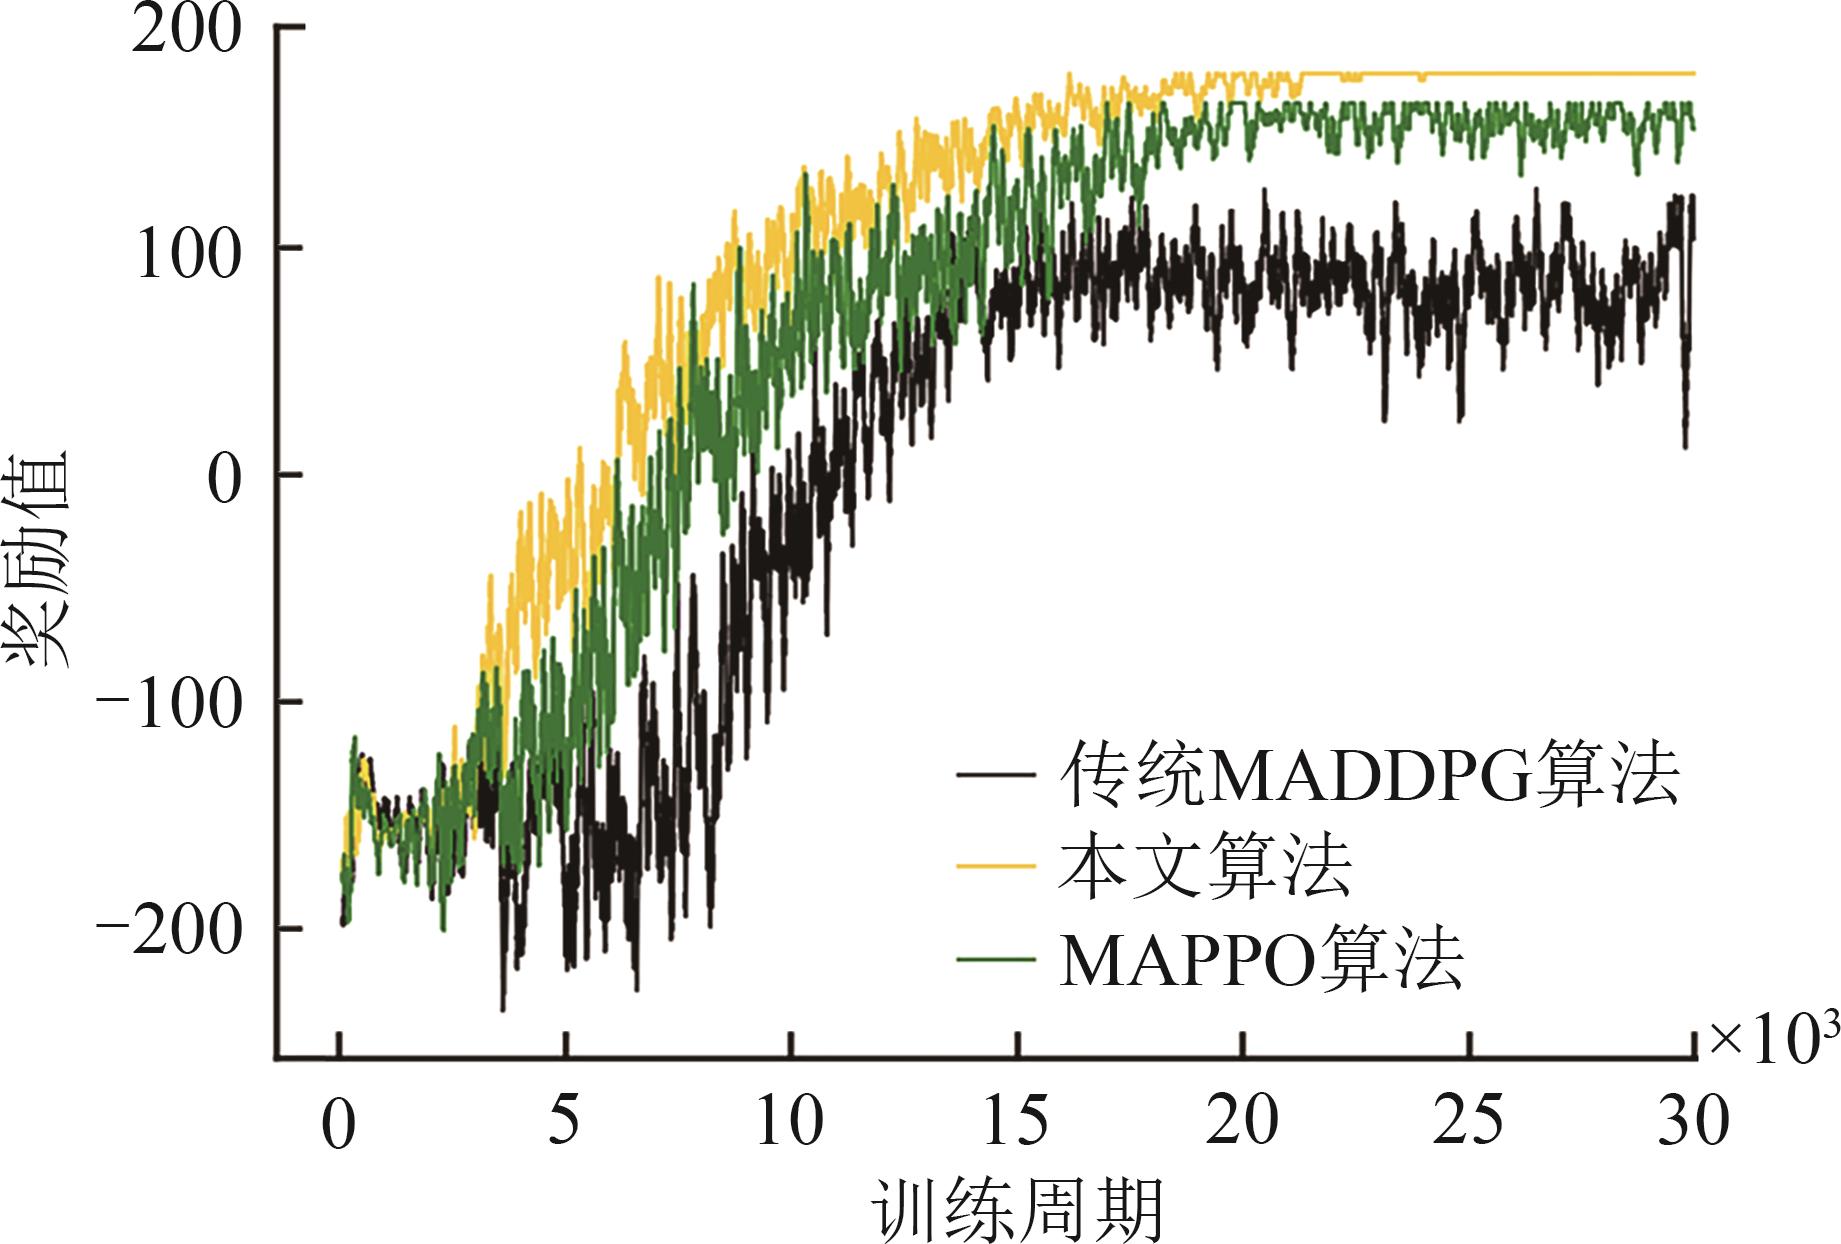
Table 3
Reward convergence comparison
| 算法 | 首次进入正奖励轮数 | 稳态奖励均值 | 后5 000轮滑动方差 |
|---|---|---|---|
| 传统-MADDPG | 12 800 | 98.2 | 187.4 |
| MAPPO | 10 500 | 121.7 | 152.6 |
| 本文算法 | 7 500 | 151.4 | 67.1 |
Fig. 12
Actor network loss function
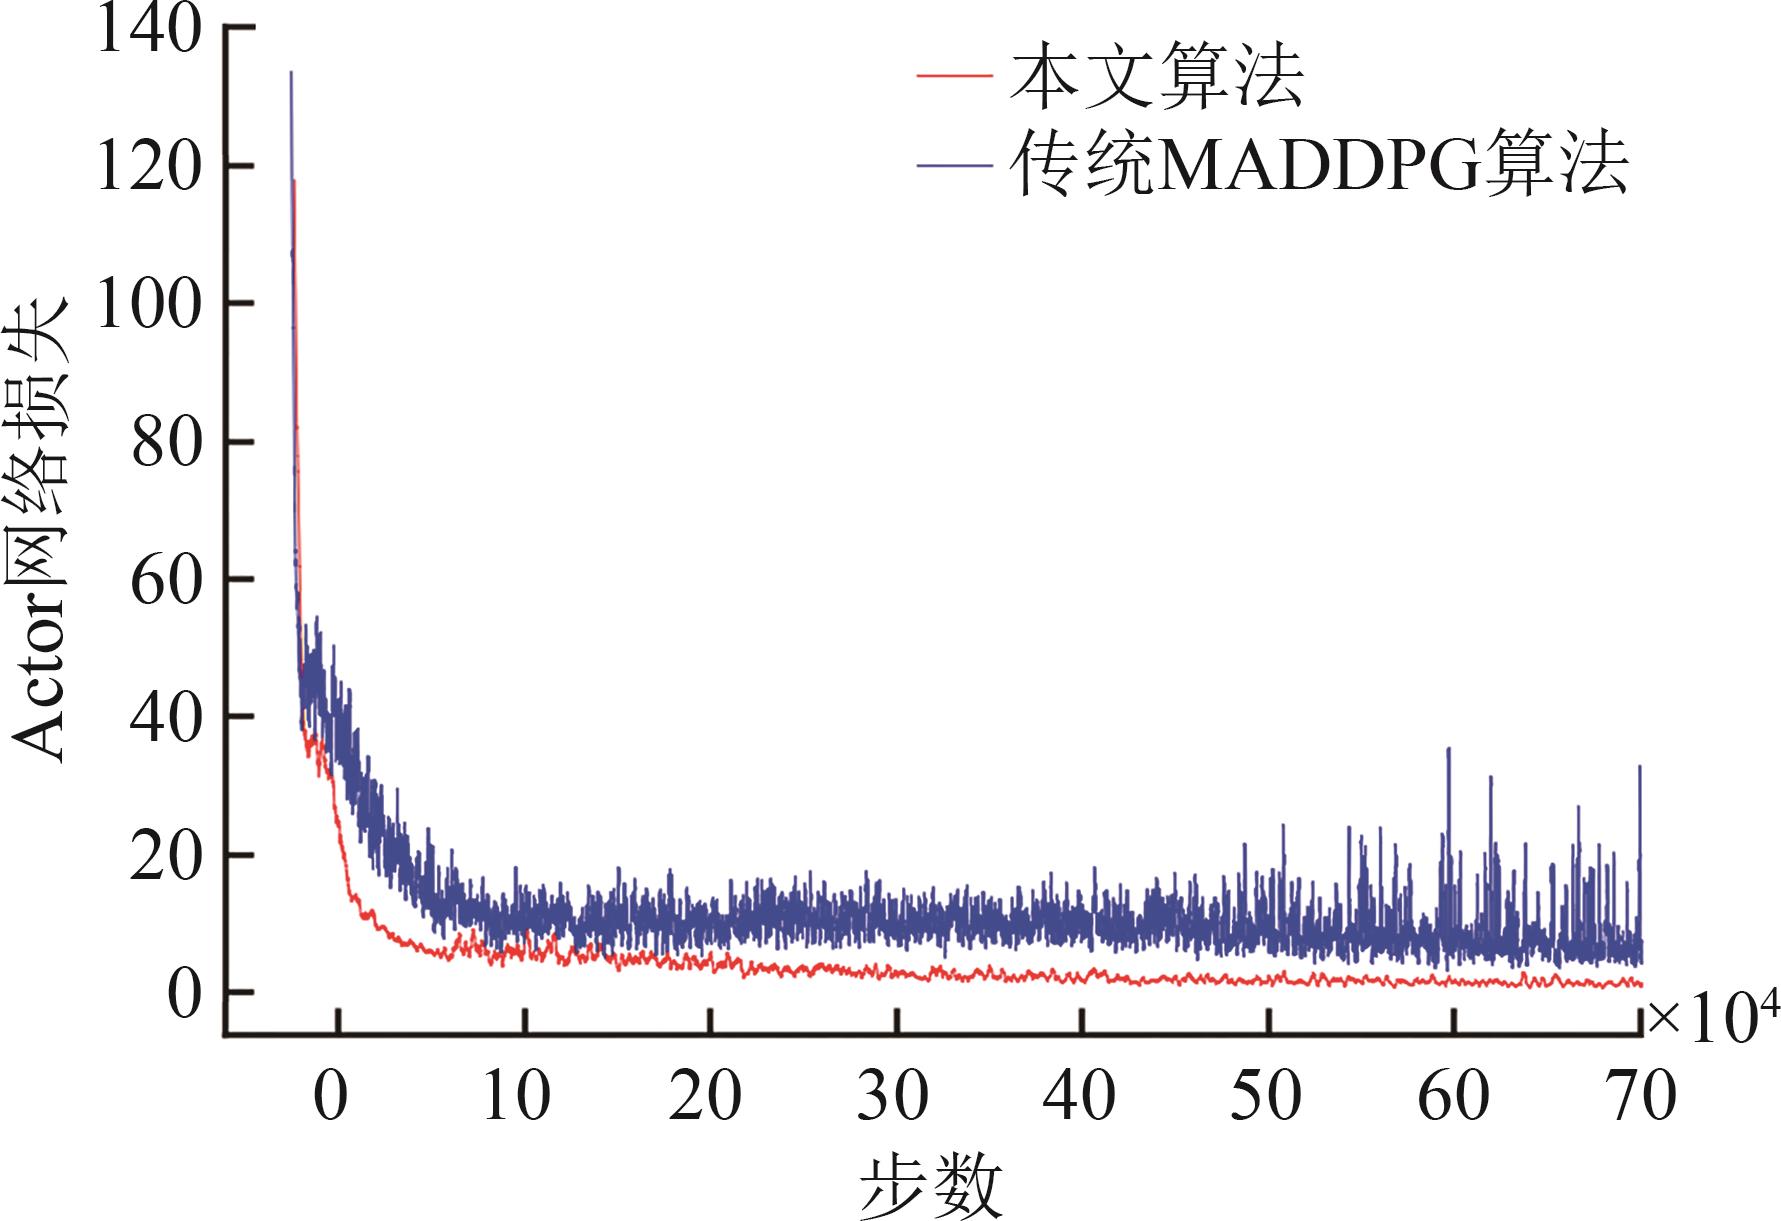
Fig. 13
Critic network loss function
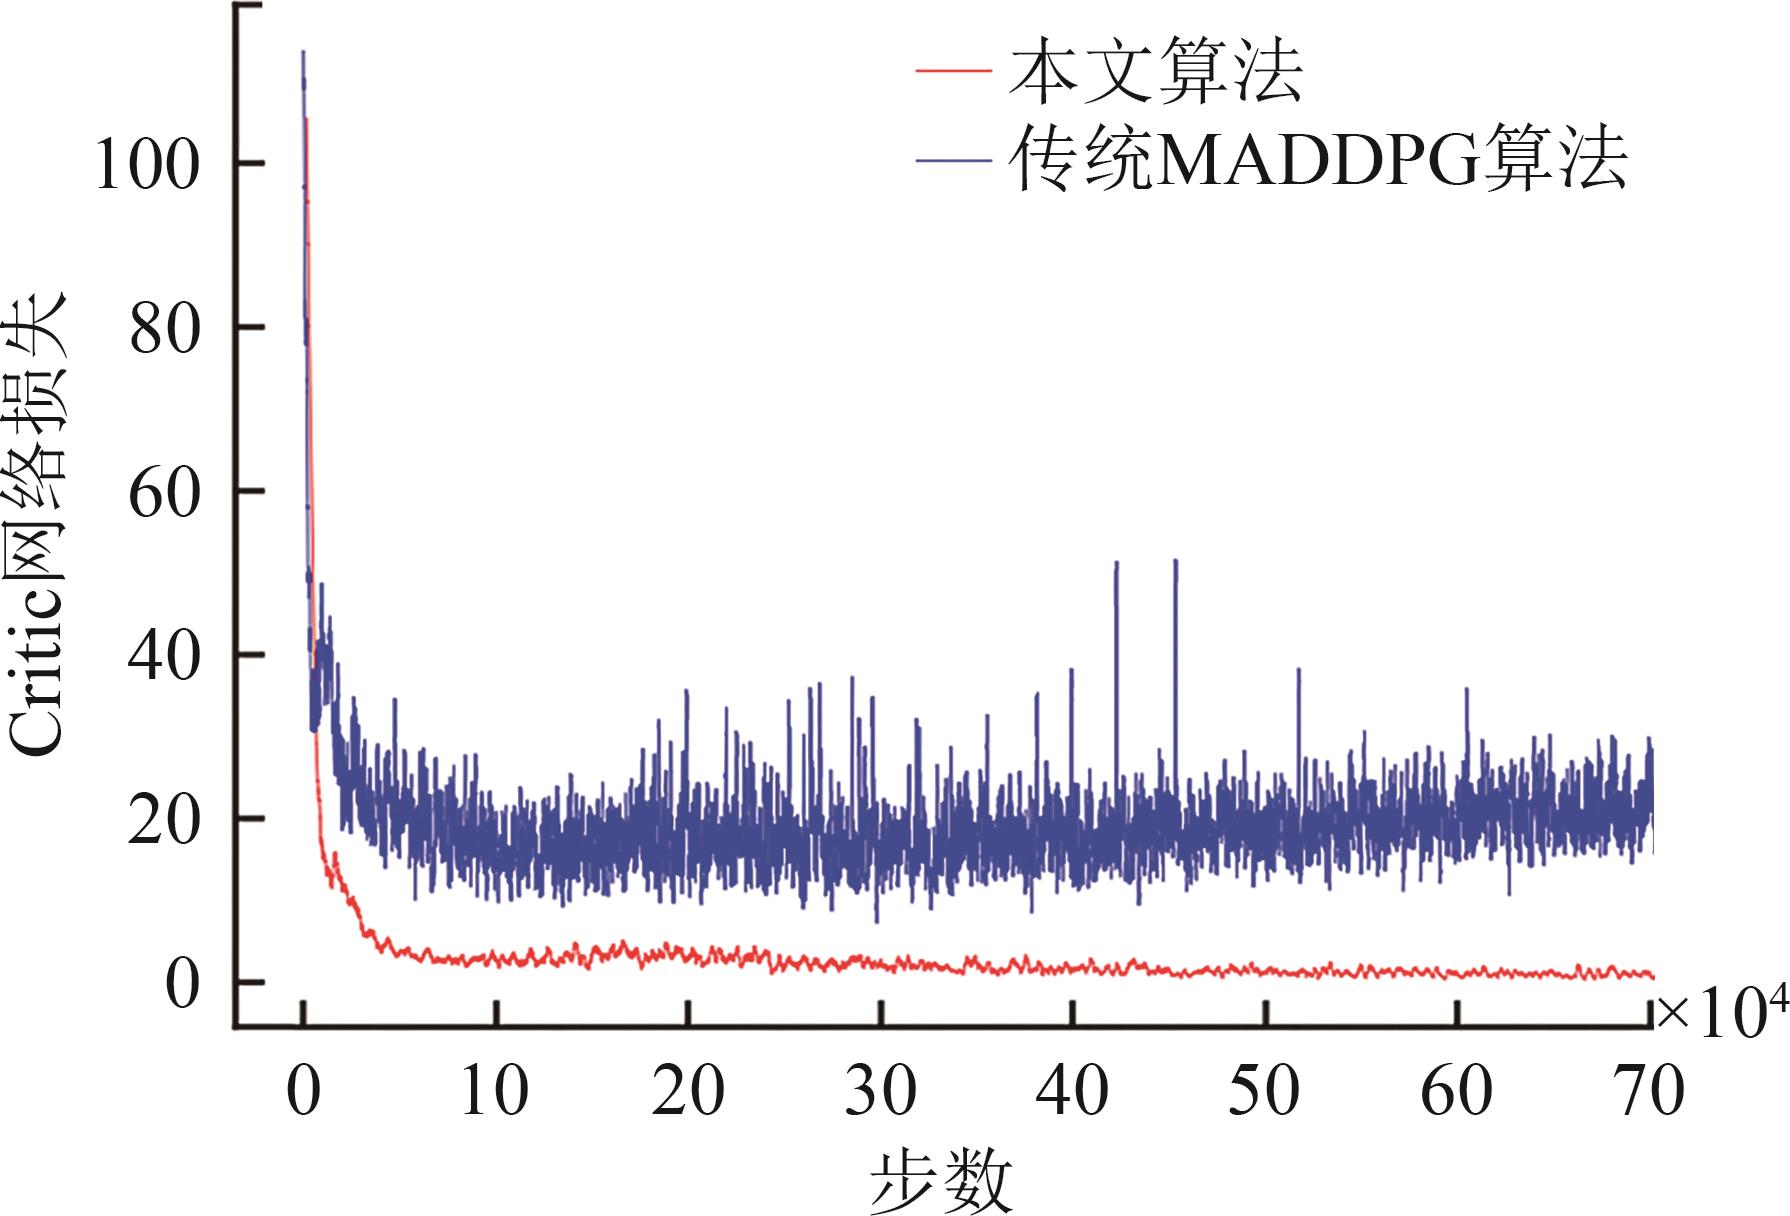
Fig. 14
Comparison of task completion situations
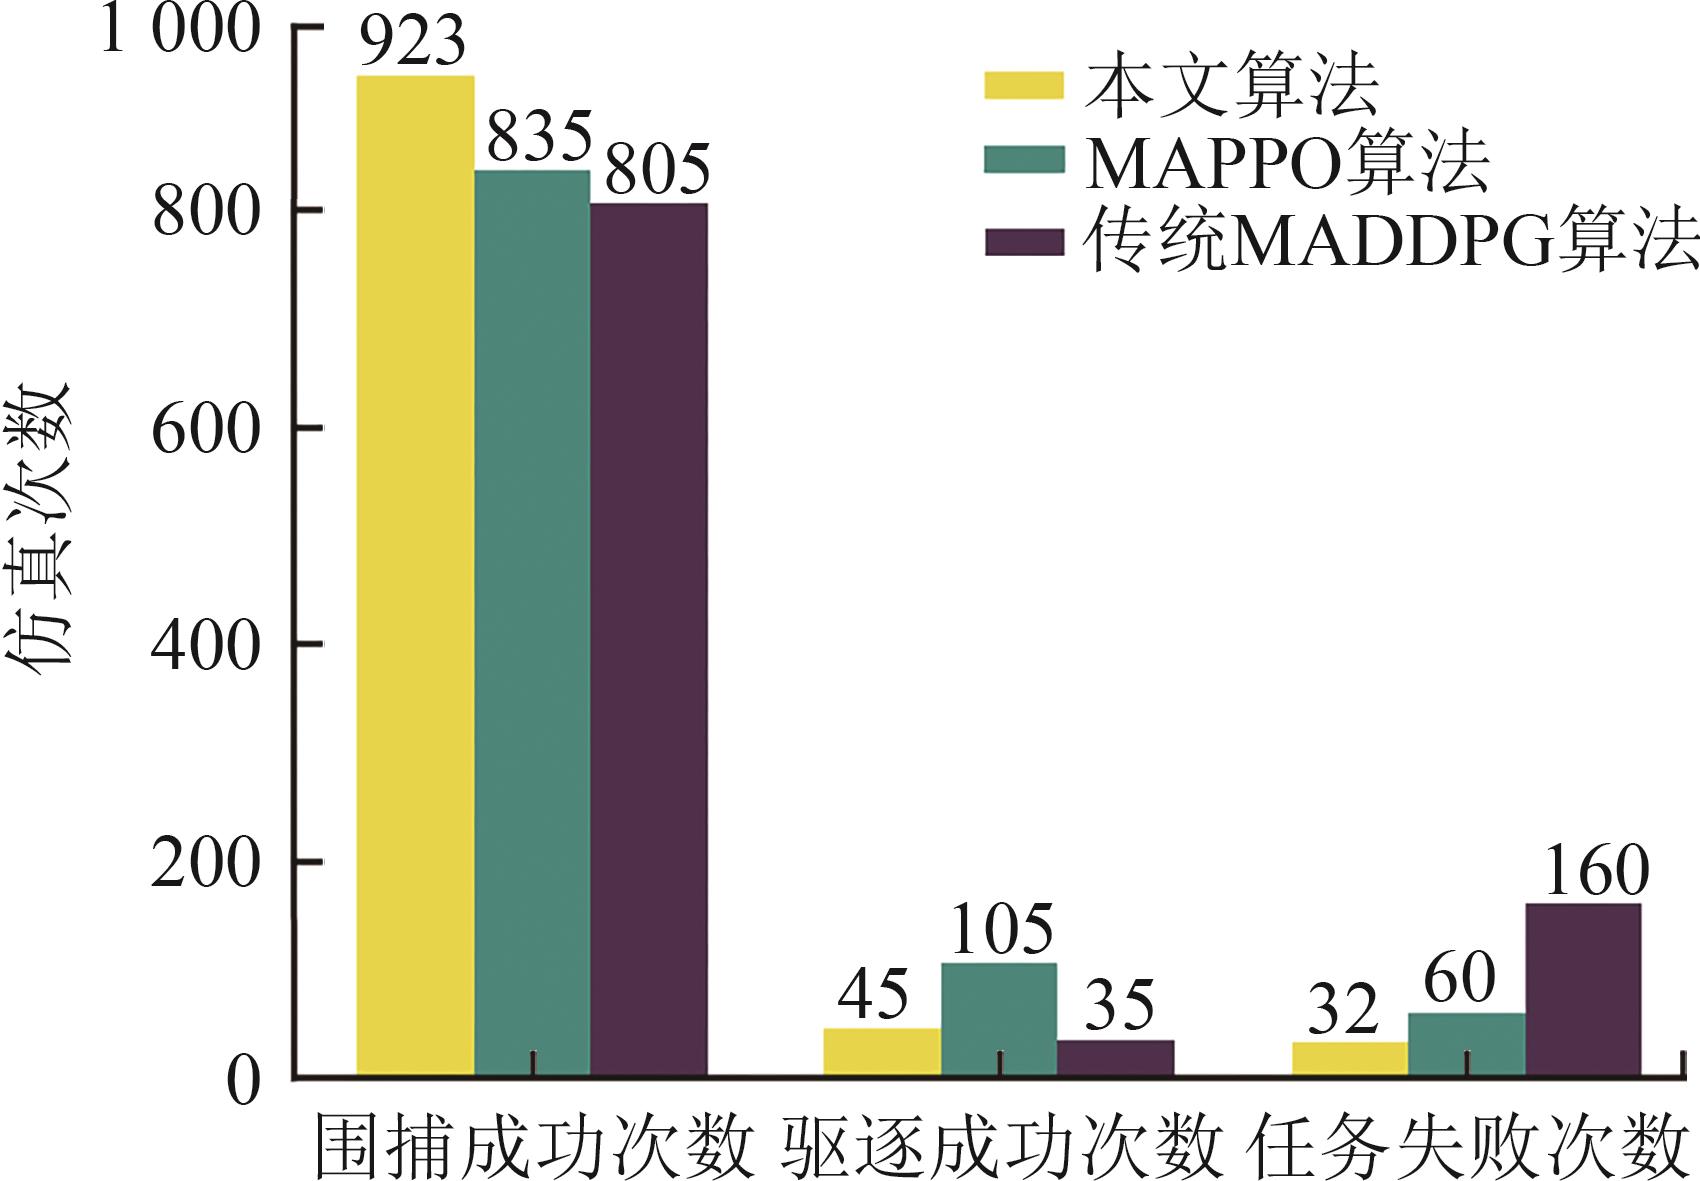
Fig. 15
Comparison of collision avoidance situations
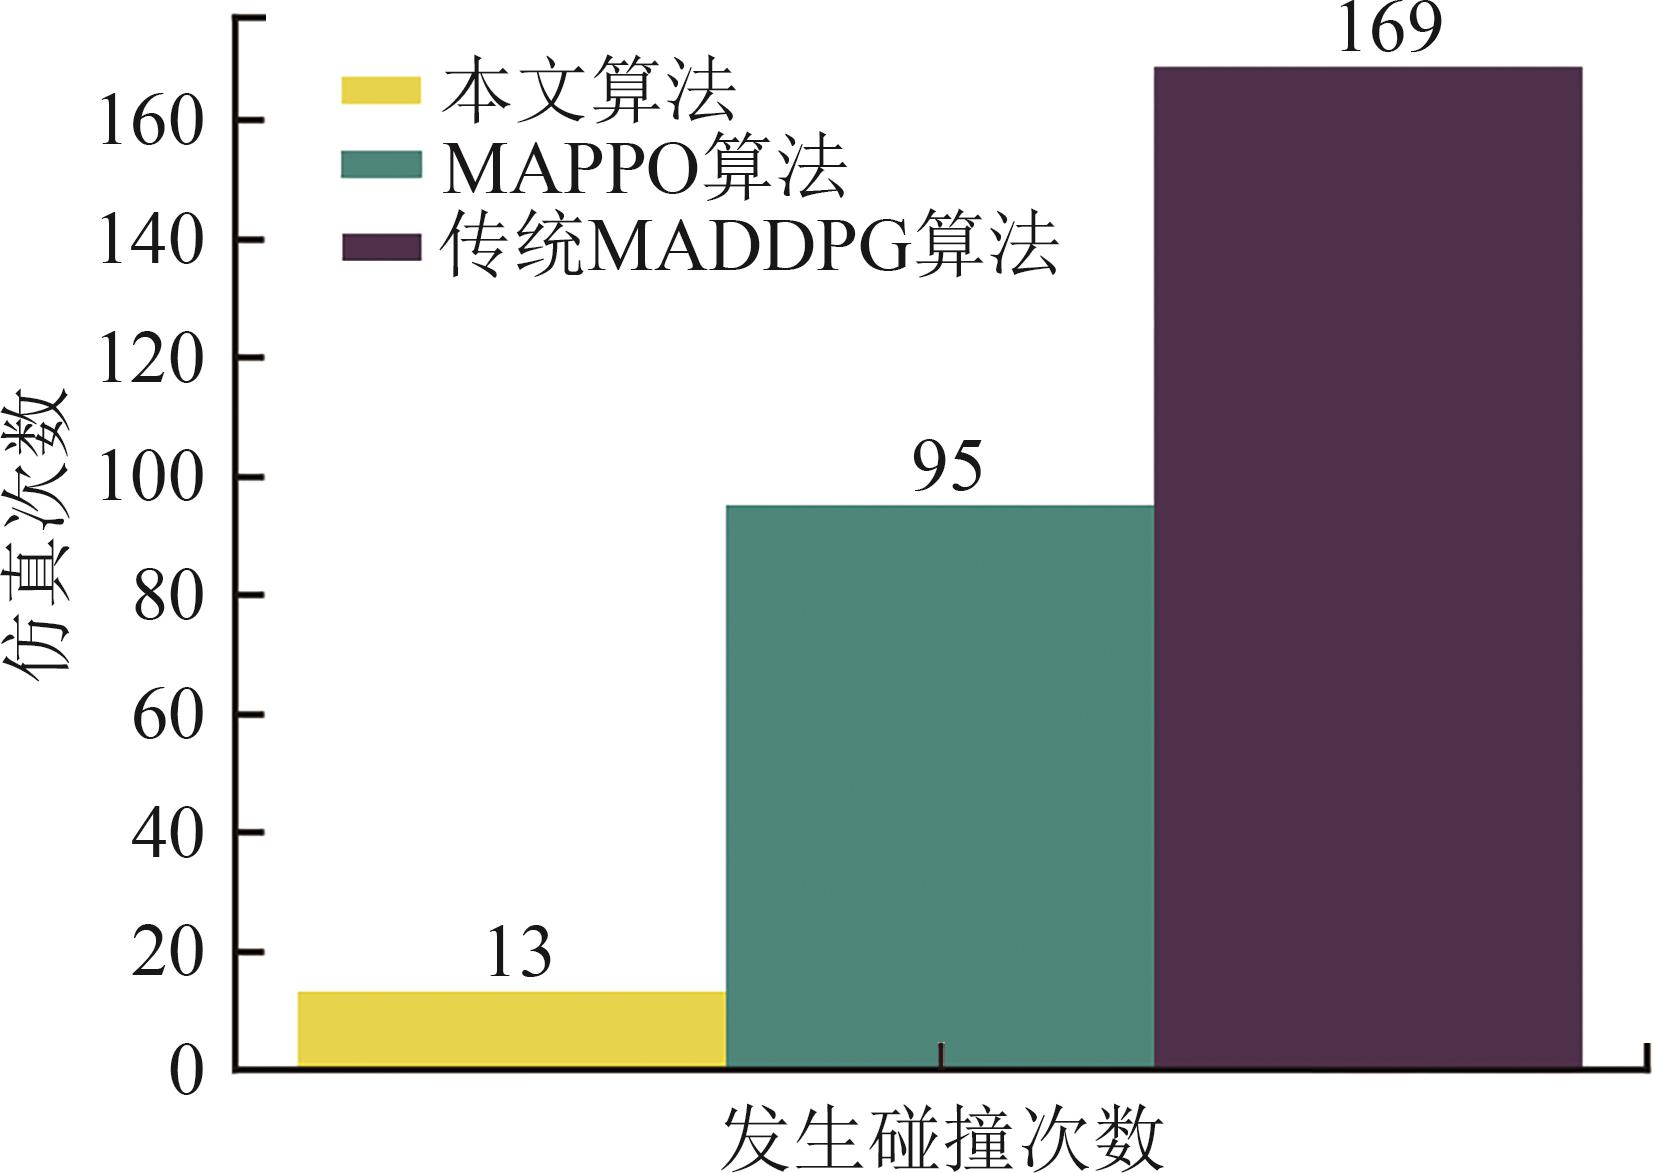
Fig. 16
Average reward comparison of five algorithms
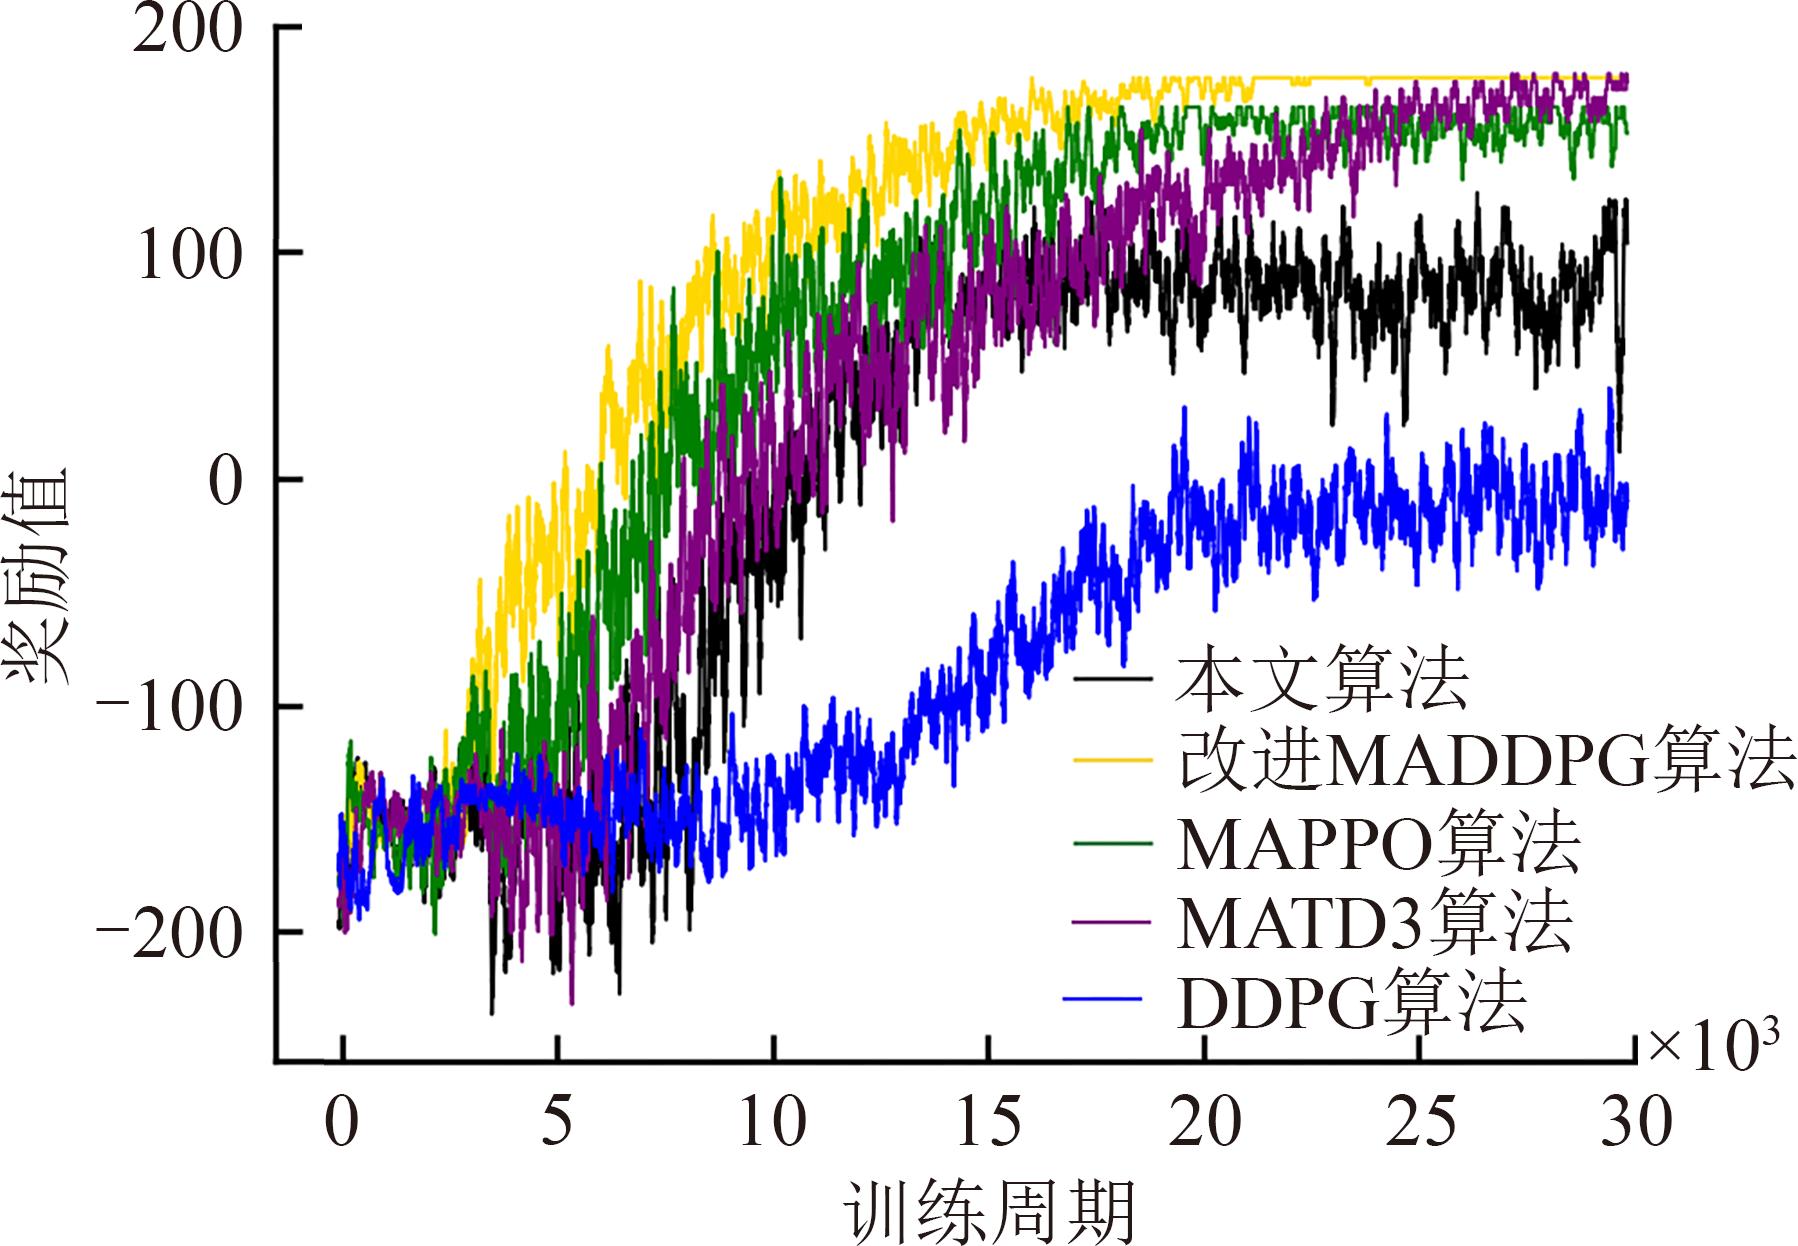
Table 4
Comparison of evaluation indicators for fivealgorithms in 1 000 Monte Carlo tests
| 算法 | 围捕 成功率 | 碰撞 规避率 | 驱逐 成功率 | 任务 失败率 |
|---|---|---|---|---|
| DDPG | 45.7 | 54.6 | 8.2 | 46.1 |
| MADDPG | 80.5 | 83.1 | 3.5 | 16.0 |
| MAPPO | 83.5 | 90.5 | 10.5 | 6.0 |
| MATD3 | 88.4 | 94.6 | 5.8 | 5.8 |
| 本文算法 | 92.3 | 98.7 | 4.5 | 3.2 |
Table 5
Robustness test results of improved MADDPG
| 工况组 | 自变量取值 | 围捕成功率/% | 碰撞规避率/% |
|---|---|---|---|
| R1 | 8 m/s | 95.0 | 99.0 |
| 10 m/s | 93.5 | 98.5 | |
| 12 m/s | 92.3 | 98.7 | |
| 14 m/s | 84.5 | 94.5 | |
| 16 m/s | 73.0 | 90.0 | |
| R2 | 2 | 76.0 | 95.5 |
| 3 | 92.3 | 98.7 | |
| 4 | 95.5 | 99.1 | |
| 5 | 97.0 | 99.4 | |
| R3 | 0 | 92.3 | 98.7 |
| 0.5 m | 91.0 | 98.0 | |
| 1.0 m | 88.5 | 96.5 | |
| 1.5 m | 84.0 | 94.0 | |
| 2.0 m | 77.5 | 90.5 |
| [1] | Liu Yuan, Chen Chao, Qu Dong, et al. Multi-USV System Antidisturbance Cooperative Searching Based on the Reinforcement Learning Method[J]. IEEE Journal of Oceanic Engineering, 2023, 48(4): 1019-1047. |
| [2] | Gan Wenhao, Qu Xiuqing, Song Dalei, et al. Multi-USV Cooperative Chasing Strategy Based on Obstacles Assistance and Deep Reinforcement Learning[J]. IEEE Transactions on Automation Science and Engineering, 2024, 21(4): 5895-5910. |
| [3] | 夏家伟, 朱旭芳, 张建强, 等. 基于多智能体强化学习的无人艇协同围捕方法[J]. 控制与决策, 2023, 38(5): 1438-1447. |
| Xia Jiawei, Zhu Xufang, Zhang Jianqiang, et al. Research on Cooperative Hunting Method of Unmanned Surface Vehicle Based on Multi-agent Reinforcement Learning[J]. Control and Decision, 2023, 38(5): 1438-1447. | |
| [4] | 石鼎, 燕雪峰, 宫丽娜, 等. 强化学习驱动的海战场多智能体协同作战仿真算法[J]. 系统仿真学报, 2023, 35(4): 786-796. |
| Shi Ding, Yan Xuefeng, Gong Lina, et al. Multi-agent Cooperative Combat Simulation in Naval Battlefield with Reinforcement Learning[J]. Journal of System Simulation, 2023, 35(4): 786-796. | |
| [5] | Wang Yueying, Wang Xin, Zhou Weixiang, et al. Threat Potential Field Based Pursuit-evasion Games for Underactuated Unmanned Surface Vehicles[J]. Ocean Engineering, 2023, 285: 115381. |
| [6] | Huang Yuyang, Li Wei, Ning Jun, et al. Formation Control for UAV-USVs Heterogeneous System with Collision Avoidance Performance[J]. Journal of Marine Science and Engineering, 2023, 11(12): 2332. |
| [7] | 赵立阳, 常天庆, 褚凯轩, 等. 完全合作类多智能体深度强化学习综述[J]. 计算机工程与应用, 2023, 59(12): 14-27. |
| Zhao Liyang, Chang Tianqing, Chu Kaixuan, et al. Survey of Fully Cooperative Multi-agent Deep Reinforcement Learning[J]. Computer Engineering and Applications, 2023, 59(12): 14-27. | |
| [8] | Xia Jiawei, Luo Yasong, Liu Zhikun, et al. Cooperative Multi-target Hunting by Unmanned Surface Vehicles Based on Multi-agent Reinforcement Learning[J]. Defence Technology, 2023, 29: 80-94. |
| [9] | Nantogma Sulemana, Zhang Shangyan, Yu Xuewei, et al. Multi-USV Dynamic Navigation and Target Capture: A Guided Multi-agent Reinforcement Learning Approach[J]. Electronics, 2023, 12(7): 1523. |
| [10] | Xue Shan, Zhao Ning, Wang Liqi, et al. Multi-agent Self-attention Reinforcement Learning for multi-USV Hunting Target[J]. Neural Networks, 2025, 189: 107574. |
| [11] | Qu Xingru, Li Chu, Jiang Yuze, et al. Cooperative Pursuit of Unmanned Surface Vehicles Using Multi-agent Reinforcement Learning[J]. Journal of Shanghai Jiaotong University (Science), 2026, 31(1): 187-194. |
| [12] | 李超, 王瑞星, 黄建忠, 等. 稀疏奖励下基于强化学习的无人集群自主决策与智能协同[J]. 兵工学报, 2023, 44(6): 1537-1546. |
| Li Chao, Wang Ruixing, Huang Jianzhong, et al. Autonomous Decision-making and Intelligent Collaboration of UAV Swarms Based on Reinforcement Learning with Sparse Rewards[J]. Acta Armamentarii, 2023, 44(6): 1537-1546. | |
| [13] | Gao Yuan, Chen Junfeng, Chen Xi, et al. Asymmetric Self-play-enabled Intelligent Heterogeneous Multirobot Catching System Using Deep Multiagent Reinforcement Learning[J]. IEEE Transactions on Robotics, 2023, 39(4): 2603-2622. |
| [14] | 孙红燕, 周洁, 陈超波, 等. 无人机集群协同免疫自学习围捕策略研究[J]. 战术导弹技术, 2023(1): 132-142. |
| Sun Hongyan, Zhou Jie, Chen Chaobo, et al. Cooperative Hunting Strategy of UAV Swarm Based on Immune Self-learning[J]. Tactical Missile Technology, 2023(1): 132-142. | |
| [15] | 孙志远. 无人艇集群协同围捕策略研究[D]. 哈尔滨: 哈尔滨工程大学, 2023. |
| Sun Zhiyuan. Research on Cooperative Pursuit Strategy of Multiple Unmanned Surface Vehicle[D]. Harbin: Harbin Engineering University, 2023. | |
| [16] | 韩慧妍, 石树熙, 况立群, 等. 改进MADDPG算法的未知环境下多智能体单目标协同探索[J]. 计算机工程与应用, 2025, 61(22): 320-328. |
| Han Huiyan, Shi Shuxi, Kuang Liqun, et al. Multi-agent Single-goal Collaborative Exploration in Unknown Environments with Improving MADDPG Algorithm[J]. Computer Engineering and Applications, 2025, 61(22): 320-328. | |
| [17] | 张红强, 石佳航, 吴亮红, 等. 改进MADDPG算法的非凸环境下多智能体自组织协同围捕[J]. 计算机科学与探索, 2024, 18(8): 2080-2090. |
| Zhang Hongqiang, Shi Jiahang, Wu Lianghong, et al. Multi-agent Self-organizing Cooperative Hunting in Non-convex Environment with Improved MADDPG Algorithm[J]. Journal of Frontiers of Computer Science and Technology, 2024, 18(8): 2080-2090. | |
| [18] | Gao Qiang, Li Shuhao, Ji Yuehui, et al. Scalable Path Planning Algorithm for multi-Unmanned Surface Vehicles Based on Multi-agent Deep Deterministic Policy Gradient[J]. Ocean Engineering, 2025, 320: 120243. |
| [19] | 张婷婷, 杨学军. 基于强化学习的城市场景下巡飞弹自主协同饱和攻击方法[J]. 指挥与控制学报, 2023, 9(4): 457-468. |
| Zhang Tingting, Yang Xuejun. Autonomous Coordination Saturation Attacks Method for Loitering Munitions in Urban Scenarios Based on Reinforcement Learning[J]. Journal of Command and Control, 2023, 9(4): 457-468. | |
| [20] | Mu Zhenxin, Pan Jie, Zhou Ziye, et al. A Survey of the Pursuit-evasion Problem in Swarm Intelligence[J]. Frontiers of Information Technology & Electronic Engineering, 2023, 24(8): 1093-1116. |
| [21] | Makkapati V R, Tsiotras P. Apollonius Allocation Algorithm for Heterogeneous Pursuers to Capture Multiple Evaders[EB/OL]. (2020-06-19) [2026-01-13]. . |
| [22] | Dorothy M, Maity D, Shishika D, et al. One Apollonius Circle is Enough for Many Pursuit-evasion Games[J]. Automatica, 2024, 163: 111587. |
| [23] | Lowe Ryan, Wu Yi, Tamar A, et al. Multi-agent Actor-critic for Mixed Cooperative-competitive Environments[C]//Proceedings of the 31st International Conference on Neural Information Processing Systems. Red Hook: Curran Associates Inc., 2017: 6382-6393. |
| [24] | He Kaiming, Zhang Xiangyu, Ren Shaoqing, et al. Deep Residual Learning for Image Recognition[C]//2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR). Piscataway: IEEE, 2016: 770-778. |
| [25] | Saglam Baturay, Mutlu Furkan B, Cicek Dogan C, et al. Actor Prioritized Experience Replay[J]. Journal of Artificial Intelligence Research, 2024, 78: 639-672. |
| [26] | Li Tengda, Wang Gang, Fu Qiang. MADDPG-D2: An Intelligent Dynamic Task Allocation Algorithm Based on Multi-agent Architecture Driven by Prior Knowledge[J]. CMES-Computer Modeling in Engineering and Sciences, 2024, 140(3): 2559-2586. |
| [27] | 符小卫, 王辛夷, 乔哲. 基于ASDDPG算法的多无人机对抗策略[J]. 系统工程与电子技术, 2025, 47(6): 1867-1879. |
| Fu Xiaowei, Wang Xinyi, Qiao Zhe. Confront Strategy of Multi-unmanned Aerial Vehicle Based on ASDDPG Algorithm[J]. Systems Engineering and Electronics, 2025, 47(6): 1867-1879. | |
| [28] | Lillicrap T P, Hunt J J, Pritzel A, et al. Continuous Control with Deep Reinforcement Learning[EB/OL]. (2019-07-05) [2026-03-18]. . |
| [29] | Ackermann Johannes, Gabler Volker, Osa Takayuki, et al. Reducing Overestimation Bias in Multi-agent Domains Using Double Centralized Critics[EB/OL]. (2019-12-02) [2026-03-19]. . |
| [30] | Fujimoto Scott, Hoof Herke, Meger David. Addressing Function Approximation Error in Actor-critic Methods[C]//Proceedings of the 35th International Conference on Machine Learning. Chia Laguna Resort: PMLR, 2018: 1587-1596. |
| [1] | Zhou Zicong, Zeng Junjie, Hu Yue, Zhu Zhengqiu, Yin Quanjun. Multi-agent Reinforcement Learning Method for Wargame Simulation Based on Suboptimal Demonstration Guidance [J]. Journal of System Simulation, 2026, 38(5): 1277-1289. |
| [2] | Gu Xueqiang, Luo Junren, Zhou Yanzhong, Zhang Wanpeng. Survey on Large Language Agent Technologies for Intelligent Game Theoretic Decision-making [J]. Journal of System Simulation, 2025, 37(5): 1142-1157. |
| [3] | Huang Zhiqin, Lu Tianying, Chen Zheyi. Multi-UAV Deployment and Collaborative Offloading for Large-scale IoT Systems [J]. Journal of System Simulation, 2025, 37(1): 25-39. |
| [4] | Ding Shi, Xuefeng Yan, Lina Gong, Jingxuan Zhang, Donghai Guan, Mingqiang Wei. Multi-agent Cooperative Combat Simulation in Naval Battlefield with Reinforcement Learning [J]. Journal of System Simulation, 2023, 35(4): 786-796. |
| Viewed | ||||||
|
Full text |
|
|||||
|
Abstract |
|
|||||
 http://www.china-simulation.com

